
The Evaluator Layer: What's Missing in Most AI Marketing Agency Stacks
See how AI marketing agencies add evaluator layers to their automation stacks, catching AI errors and quality drift before any content reaches audiences.
10 December 2025Team COEY
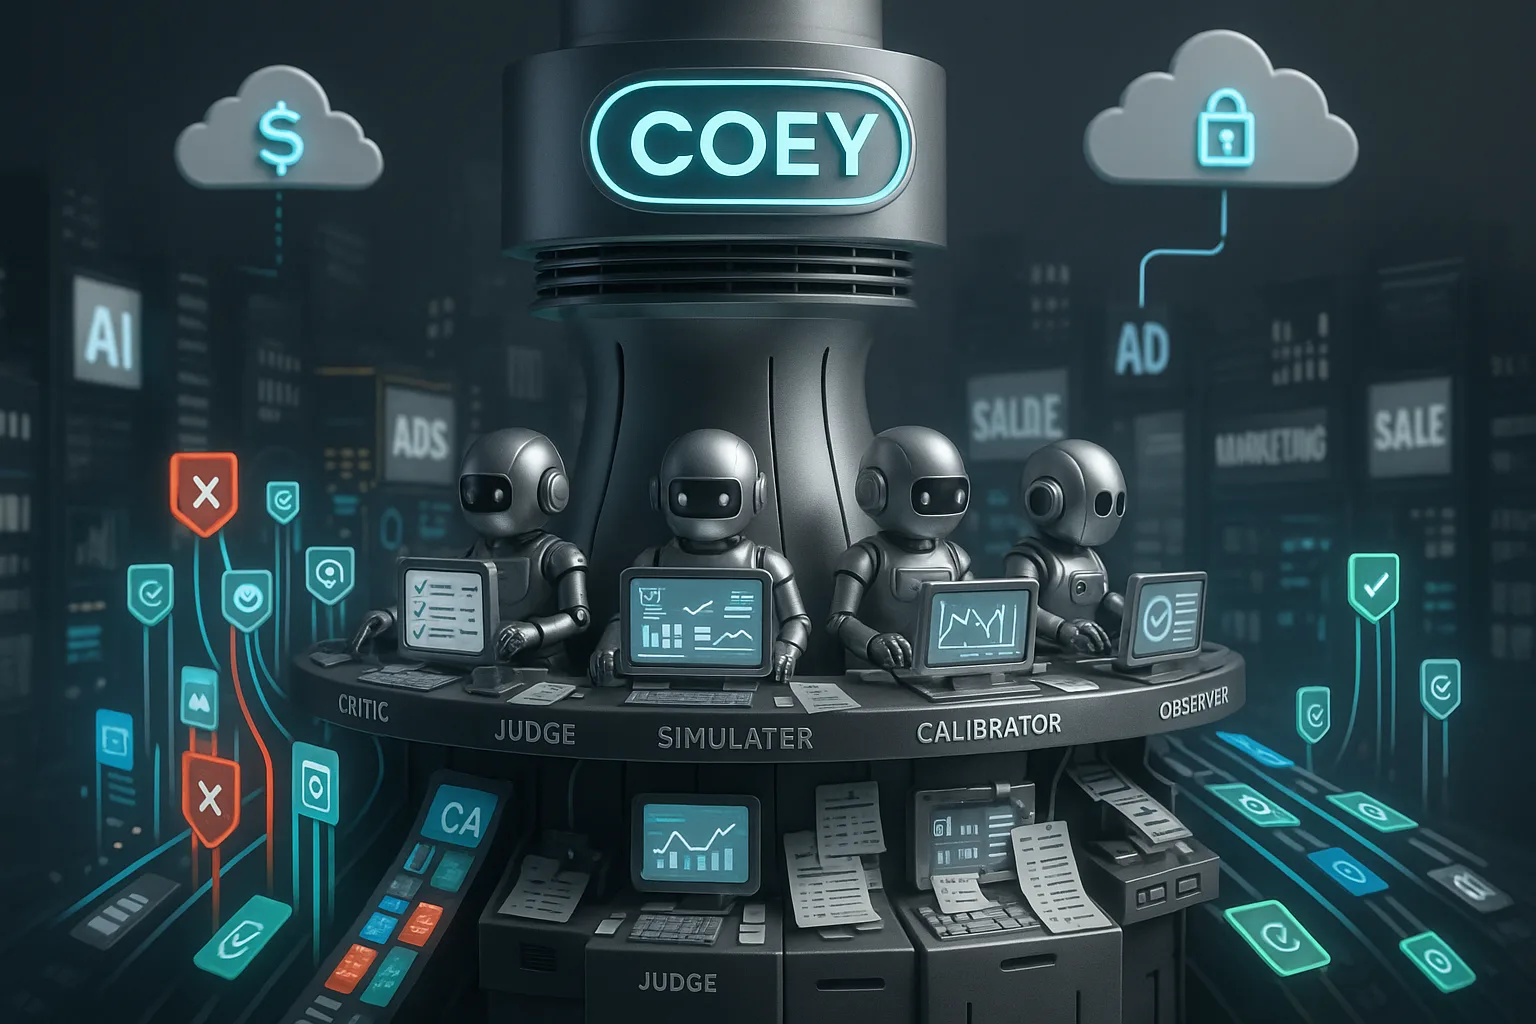
Forget pitching flashy new models. Marketers have seen enough Franken intelligences promising “synergy” and “hyperautomation.” Real transformation happens in the shadows, where automation’s grown ups keep the show running. Enter the evaluator layer, the overlooked command tower now central to AI powered marketing. Its job: enforce structure, verify provenance, call out garbage, predict what actually works, and relentlessly keep everything slotted into what you are measured on. Without it, your agents drift off brand, your budgets bleed, and your lawyers start drinking decaf.
Why the sudden rush? Three shifts changed the board. Platforms are adding content credentials and verification features that favor traceable media, see Google’s recent work on trusted image credentials and verification across Pixel and Android and new verification features in the Gemini app for image authenticity. Explainable AI is no longer a lab toy. It is expected in front of your compliance lead or finance chief. Models are graduating from “generate stuff” to “critique, rank, and simulate.” Evaluators are not research candy. They are the most valuable and the most underappreciated piece of your automation stack. For distribution strategy and licensed retrieval, see our take on the shift to eligibility and receipts in Welcome to the Licensed Retrieval Era.
Why This Shift Matters Now
Distribution rewards receipts, not vibes. Assistants, feeds, and search favor content with a paper trail. Every asset should pass eligibility, rights, and freshness checks before release.
Generation is cheap. Choices are precious. Flood the zone with options if you want, but only evaluators will sort winners from wastes under time, brand, and spend constraints.
Models now judge, not just generate. Judge models and checklist evaluators provide explainable scoring. Goodbye endless debates over “intent.”
Budgets have new teeth. Cloud costs are not about how many tokens you eat. They are about who calls for retries, who escalates for humans, and who routes to premium versus frontier models. Evaluators write these rules, not your prompts.
Evaluator Types That Actually Ship
| Evaluator | Job | Where It Fits | Primary Output | Biggest Risk |
|---|---|---|---|---|
| Critic | Enforce structure, rights, locale, claims, accessibility, cost | Gatekeeper before publish, everywhere | Pass/fail + repair suggestions | Overfitting rules; false negatives block useful content |
| Judge | Score quality, clarity, fit, risk (per rubric) | Variant selection, routing | Scorecard, ranked picks, reasons | Style bias; stagnation |
| Simulator | Predict audience response, per channel/persona | Preflight creative, UX/offer tuning | Predicted lift, friction, risky copy | Poor calibration; mismatch with live |
| Calibrator | Align evaluation to real KPIs, auto tune | Tuning loop, versioning | New weights and cutoffs | Silent metric drift; lost explainability |
| Observer | Monitor ops, audits, drift, cost | Dashboards, defect flagging, anomaly surfacing | Alerts, trends | Alert fatigue; missed issues |
Evaluator Layer: Blueprint in Practice
[Truth]
  → product specs • pricing • policies • rights • glossary
[Generate]
  → schema-bound drafts • variants • localizations
[Evaluate]
  → critics • judges • simulators • calibrators
[Route]
  → small-fast models • escalate on risk/ambiguity
[Publish]
  → CMS • ads • email • all assistants
[Receipts]
  → sources • model route • cost • reviewer • decision
[Observe]
  → quality • cost • drift • inclusion • escapes
Pro tip: Evaluator layers are not monoliths. They are cell sized policies, templates, and micro services, called the same predictable way at every gate. Scorecards beat opinions.
Why Critics Go First
{
  "critics": {
    "structure": {"schema_id": "AnswerCardV14", "enforce": true},
    "claims": {"numeric_require_source": true, "allow_from": ["lab", "ops", "pricing"]},
    "rights": {"license_token": "required", "territory_lock": true, "expiry_required": true},
    "locale": {"currency": "auto", "date": "auto"},
    "accessibility": {"alt_text": true, "contrast_min": 4.7},
    "cost_guard": {"max_cost_per_asset_usd": 1.50, "retry_limit": 1}
  }
}
No adjectives required. Critics enforce facts, format, and policy. No sentiment needed. If an asset fails, fix it once, escalate if needed, and never let it loop forever. That is how you nuke a cloud bill.
Automate This With COEY
COEY helps brands and agencies turn strategies like this into real, running automation. We connect tools like n8n, Claude, and OpenClaw into workflows that actually ship. Explore our AI automation services or request a proposal.