
Provenance on every asset that ships
Learn how to build a reliable AI content provenance workflow that keeps your creation process trustworthy and ready for new ad and regulatory rules. This hands-on guide covers risk classification, approval layers, documentation, and how to combine AI with clear human policies, without slowing your team down. Includes schema examples, system blueprints, and operational tips in COEY's signature voice.
2 August 2026Team COEY
Most teams do not have an AI generation problem anymore. They have a trust problem.
Content gets drafted in one tool, edited in another, approved in Slack, shipped through an ad platform, then screenshot by strangers who absolutely do not care that your internal process doc said “final final real one.” Somewhere in that mess, a simple question becomes weirdly hard to answer: what was made by AI, what was changed by humans, what needs disclosure, and who approved it?
That question matters even more now because Google’s expanded AI ad transparency layer is live, the EU AI Act transparency guidance is now operational, and platforms are increasingly less patient with low-quality synthetic sludge. Very cool time to keep winging it.
The goal is not to slow creation down. It is to build a system where humans define policy, review risk, and approve public assets while AI helps document, classify, and route the work.
This is where an AI content provenance workflow becomes useful. Not as compliance theater. As operating infrastructure.
What problem this workflow solves
Most organizations cannot reliably answer basic provenance questions at scale:
Was this asset generated, edited, or translated with AI?
Did it include a synthetic person or voice?
Does this ad require disclosure in a given market?
Which version actually got approved?
Can we prove what changed between draft and launch?
If a platform asks for documentation, do we have receipts or vibes?
A provenance workflow fixes the ugly middle between content creation and public distribution.
It helps you:
capture AI usage across text, image, audio, and video workflows
classify asset risk before publishing
separate human edits from machine-generated output
trigger disclosure checks automatically
store approval and revision history
create an audit trail without making your team hate life
Why this topic matters right now
Three shifts make provenance more operational than theoretical.
Google Ads transparency is expanding. New AI labeling and “how this ad was made” disclosure paths are now much more embedded in the ad workflow.
EU transparency obligations are now very real. As of August 2, 2026, Article 50 enforcement is no longer a future-you problem.
Platforms are getting less patient with AI slop. Synthetic content that is misleading, lazy, or unlabeled is becoming a faster route to distrust and performance pain.
Meanwhile, HubSpot, Klaviyo, Salesforce, and the rest of the go-to-market stack keep getting more agent-shaped. That means more content can be created faster, inside more workflows, by more non-specialists. Great for speed. Also a fantastic way to lose track of what was actually made.
So no, provenance is not just for journalists or deepfake panic threads. It is now a marketing ops issue.
The mental model
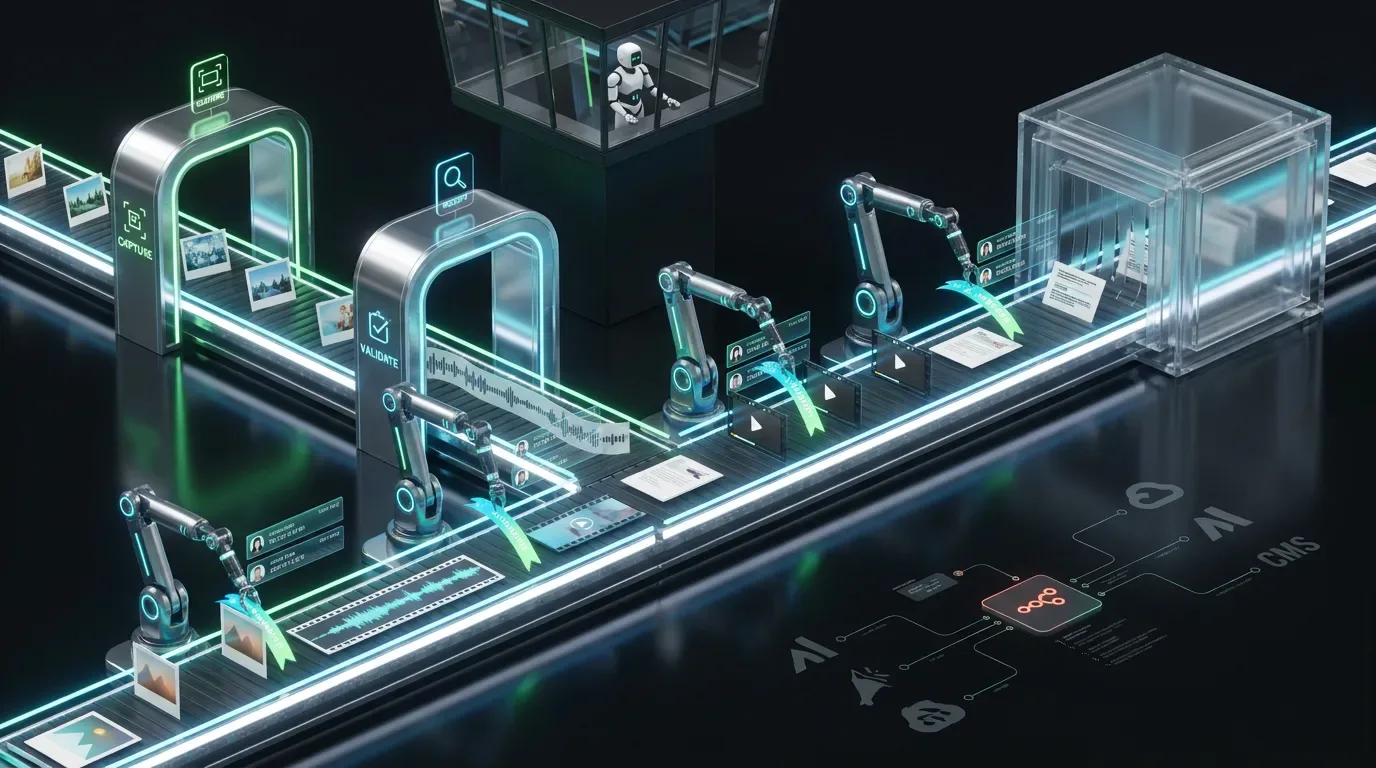
Think of provenance as a five-layer workflow.
| Layer | What it does | Human role |
|---|---|---|
| Capture | Records where AI touched the asset | Define required metadata fields |
| Classification | Determines content type, synthetic elements, and risk | Set policy categories and thresholds |
| Validation | Checks disclosures, policy rules, and market requirements | Own legal and brand rules |
| Review | Routes risky assets to humans | Approve, edit, reject, escalate |
| Receipt | Stores version history and approvals | Maintain accountability |
The key idea is simple: automate documentation and routing, not final judgment.
If your system can generate an ad with a synthetic spokesperson, skip the disclosure check, and publish it because nobody asked the right question, that is not automation. That is a brand risk speedrun.
Tools and systems involved
A practical stack might include:
Orchestration: n8n
Creation tools: your CMS, ad tools, image tools, video tools, email platforms, AI writing tools
Storage: Airtable, Notion, Google Sheets, or a lightweight database
Approval layer: Slack, Asana, Notion, Airtable, or an internal review queue
LLM layer: one fast structured-output model for classification and one stronger model for ambiguous policy cases
Destination systems: ad platforms, CRM, CMS, DAM, email service providers
Why n8n? Because provenance is not a single app feature. It is a systems problem. You need triggers, metadata capture, conditional logic, review steps, logging, and downstream updates. This is exactly the kind of unglamorous but high-leverage plumbing that separates real automation from prompt cosplay.
For the LLM layer, keep your model references current. Today that means evaluating current families for structured policy work, not naming retired favorites like they still run the building.
Where AI adds leverage
AI is useful here for classification, summarization, and policy routing.
It can:
classify whether an asset is AI-generated, AI-edited, human-authored, or mixed
detect likely synthetic elements like avatars, voice clones, or AI image composites
summarize which tools and steps were used in production
flag assets that likely require disclosure
prepare clean review packets for legal, brand, or performance teams
draft internal provenance notes for storage and audit
That matters because nobody should manually inspect every asset’s production history across six tools unless your org chart currently includes “forensic meme detective.”
Where humans must stay in control
defining what counts as AI-generated versus AI-assisted
setting disclosure requirements by market and platform
reviewing high-risk content such as synthetic performers, political adjacency, health, finance, or public claims
approving exceptions and edge cases
deciding what gets published when rules conflict or context gets weird
If your system treats “AI helped resize a banner” and “we invented a photorealistic fake person for an ad” as the same thing, your policy layer is asleep at the wheel.
Guardrails to define before launch
| Guardrail | Implementation | Why it matters |
|---|---|---|
| Required provenance fields | Capture AI usage, tool source, synthetic elements, editor, market, and destination | Stops the workflow from guessing |
| Risk tiers | Classify assets as low, medium, or high risk by content type and market | Ensures the right review path |
| Approval gates | Require human signoff for high-risk synthetic content | Protects brand and compliance |
Also useful:
store a version hash or asset ID for every publishable file
separate observed production facts from AI-inferred risk notes
log every approval action with timestamp and reviewer
maintain a market rules table outside the prompt layer
default unknown cases to review, not auto-pass
The workflow blueprint
Step 1: Define what provenance means in your organization
Do not start with tech. Start with policy.
You need a shared taxonomy for questions like:
What counts as AI-generated?
What counts as AI-assisted editing?
What counts as a synthetic performer?
When does disclosure become mandatory?
Which destinations have their own special rules?
Keep it boring and explicit. Boring systems survive lawyers.
Example categories:
human-authored
AI-assisted copy edit
AI-generated text draft
AI-generated image
AI-edited image
synthetic voice
synthetic human likeness
mixed media composite
Step 2: Create a provenance intake schema
Every asset entering the workflow should map to one consistent record.
{
  "asset_id": "",
  "asset_type": "image|video|audio|text|ad",
  "campaign_name": "",
  "destination_channel": "",
  "market": "",
  "ai_usage_type": "ai_generated|ai_edited|human_only|mixed",
  "synthetic_elements": ["synthetic_voice", "synthetic_person"],
  "tools_used": [""],
  "human_editor": "",
  "source_file_link": "",
  "risk_tier": "low|medium|high"
}
This is the difference between a controlled workflow and an archaeological dig through Slack threads.
Step 3: Capture metadata automatically where possible
Do not rely on humans to remember every tool touch if the systems already know.
Your workflow can pull signals from:
CMS metadata
ad intake forms
file upload steps
AI generation logs
creator submission forms
DAM tags
Humans should confirm and correct metadata, not invent it from memory after launch panic.
Step 4: Use AI to classify ambiguous assets
Some cases will be obvious. Others will be messy.
Ask the model for structured output, not a thoughtful essay about authenticity.
{
  "provenance_summary": "",
  "likely_ai_usage": "human_only|ai_generated|ai_edited|mixed|uncertain",
  "synthetic_element_flags": [""],
  "disclosure_likely_required": true,
  "reasoning_notes": [""],
  "confidence_score": 0,
  "human_review_required": true
}
This helps the workflow route cleanly without pretending the model is your compliance department.
Step 5: Apply deterministic rules before approval
Run rules outside the model whenever possible.
If market equals EU and asset is AI-generated or manipulated in a covered context, route to disclosure review.
If destination is Google Ads and AI-edited creative is flagged, require disclosure confirmation.
If synthetic performer is present, route to market-specific legal review.
If provenance fields are incomplete, block publishing.
If confidence is low, escalate.
This is systems work. Not prompt wizardry. Thank goodness.
Step 6: Route by risk level
Low risk: AI-assisted copy cleanup, basic image edits, internal content
Medium risk: public marketing assets with AI-generated visuals or voiceover
High risk: synthetic humans, regulated categories, executive communications, political or public-interest adjacency
Low-risk items may only need lightweight logging. High-risk items should stop for human review before distribution.
Step 7: Build a human review packet that does not waste time
Your reviewer should get:
asset preview or file link
destination and market
captured provenance record
AI classification summary
required disclosure recommendations
approve, edit, reject, or escalate actions
Do not make reviewers reconstruct what happened from tool confetti.
Step 8: Store receipts after approval
Once approved, log:
final asset version
approval status
reviewer name
disclosure decision
publish destination
timestamp
This is the part that saves you later when somebody asks who approved the AI spokesperson with six fingers and a suspiciously perfect jawline.
What this looks like in n8n
Webhook or form trigger from asset intake
File or metadata pull from source system
Set or Function node for normalization
LLM node for classification and structured risk output
JSON validation step
IF and Switch nodes for market and risk routing
Create approval task in Slack, Airtable, Notion, or Asana
Wait for approval
Update DAM, CMS, ad record, or archive table
Store receipts and final review notes
Model selection without becoming a compliance goblin
| Use case | Best fit | Why |
|---|---|---|
| Metadata classification | Fast lower-cost model | Cheap structured output at scale |
| Risk summarization | Balanced model | Better nuance for mixed assets |
| Edge-case review support | Stronger reasoning model | Better abstention and explanation |
You do not need a premium model to read a form field and notice that a video includes synthetic narration. Save the expensive reasoning for cases where policy gets fuzzy.
How to measure success
| Metric | What to measure | Why it matters |
|---|---|---|
| Provenance capture rate | Percent of published assets with complete provenance records | Shows workflow coverage |
| Review accuracy rate | Percent of routed assets judged correctly by reviewers | Shows classification quality |
| Time to approved publish | Time from asset intake to final review decision | Shows whether governance is usable |
Tradeoffs and constraints
not every tool exposes clean metadata
AI classification is useful, but not a legal ruling
too many review gates can create bottlenecks
too few guardrails can create compliance drama at machine speed
market rules change, so your workflow needs updating like any other system
Also, provenance is not the same as truth. It helps document how something was made and how it was approved. It does not magically make bad content good.
Why this is really a systems problem
Anyone can add an “AI used yes or no” checkbox.
The hard part is building a system where asset metadata, risk logic, disclosures, approval rules, and publication records all stay connected from draft to launch.
That is not a tooling problem alone. It is a systems design problem.
Humans still define what responsible use looks like, where disclosure matters, and what risk the brand is willing to carry. AI helps classify, summarize, and route the mess. Automation makes that process repeatable. If you want the broader strategic case for why this matters, COEY also covered it in Why Provenance Is the New Marketing Must-Have.
Humans define the rules. AI documents and flags the work. Systems make trust operational.
That is how you build an AI content provenance workflow without turning compliance into a bottleneck or marketing into a screenshot waiting to happen.