Visibility from the assistants that cite you
Learn to build an AI visibility reporting workflow that goes beyond dashboards, connecting prompt tracking, answer capture, classification, and actionable insights using tools like n8n. This guide covers why legacy traffic and attribution models fall short in the age of AI answers, how to set up layered reporting systems, where humans and AI each add value, and how to orchestrate the process for repeatable business outcomes. Includes step-by-step process, example frameworks, and practical tips for measurement and action.
16 August 2026Team COEY
How to Build an AI Visibility Reporting Workflow
n8n is a strong orchestration layer for AI visibility reporting because this is not a dashboard trick. It is a systems problem. Traffic reports used to make marketers feel safe. Then AI answers, zero-click discovery, and chatbot-first interfaces showed up and politely stole the old map.
Now your brand can influence a buying decision without earning a site visit, a tracked session, or a neat little attribution path your dashboard can hug at night.
That does not mean measurement is dead. It means your measurement model is overdue for a rebuild.
This is where an AI visibility reporting workflow becomes useful. Not as a vanity scoreboard. As an operating system for understanding how your brand appears across AI-driven discovery surfaces, how often it is cited or mentioned, how it is framed, and what actions humans should take next.
The goal is not to automate strategy. It is to build a governed system where humans define what visibility matters, what counts as brand-safe representation, and what requires intervention, while AI helps collect, classify, summarize, and route the signal.
What problem this workflow solves
Most reporting stacks still assume the user journey begins with a click. That breaks in a world where buyers increasingly get answers before they ever reach your site.
Without a dedicated workflow, teams struggle to answer basic questions:
Is our brand being mentioned in AI answers at all?
Are we cited as a source, or just paraphrased into the void?
Is the framing accurate, favorable, and strategically useful?
Which topics are we visible for, and which are owned by competitors?
When AI surfaces our brand, does it push users toward action or not really?
A practical AI visibility workflow fixes the ugly middle between our content exists somewhere in the machine layer and we can measure, review, and improve how our brand shows up there.
This matters even more now because the market is maturing fast. Google keeps pushing AI discovery deeper into search with Search AI Mode updates, while orchestration platforms like n8n keep expanding AI workflow controls in current releases. In other words, this is no longer a weird side project for SEO goblins. It is a board-level discoverability problem.
The mental model
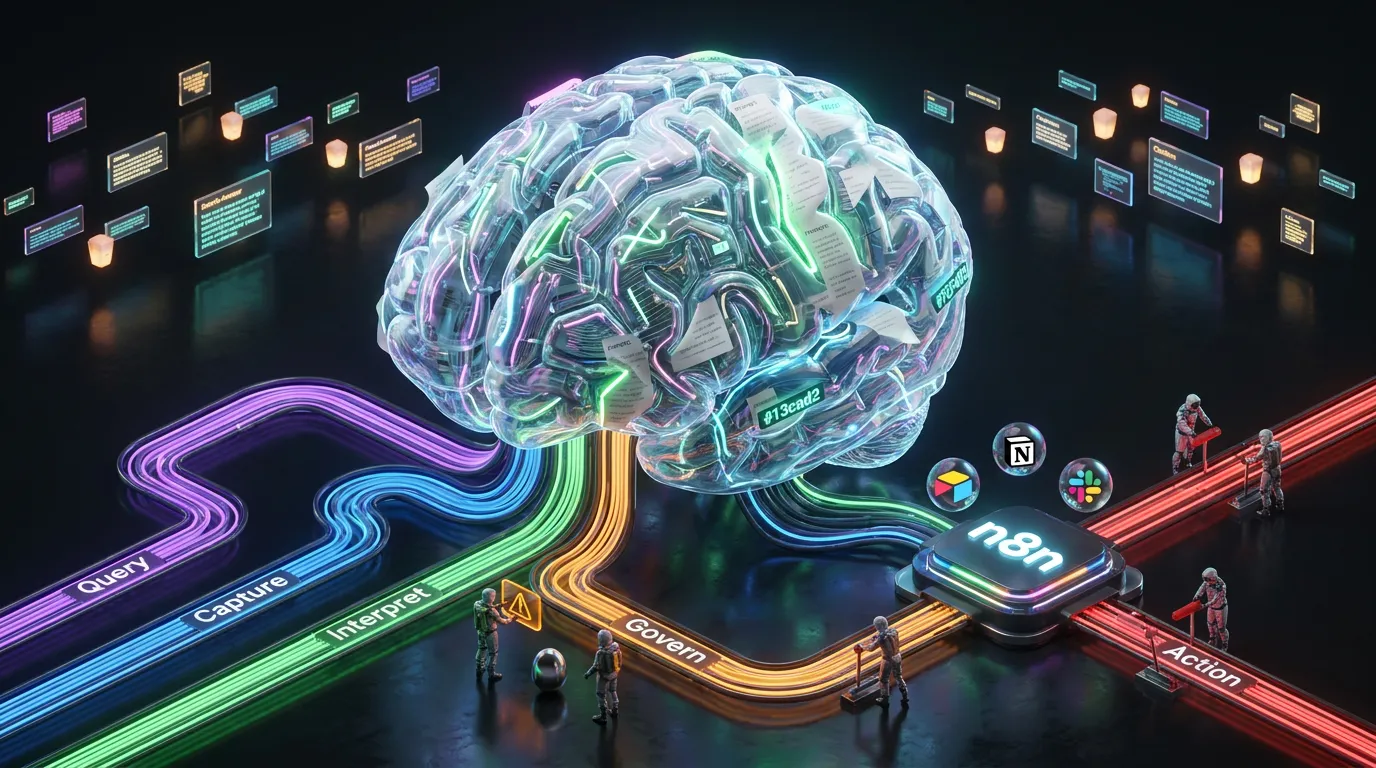
Think of AI visibility reporting as five layers.
| Layer | What it does | Human role |
|---|---|---|
| Query design | Defines the prompts, questions, and scenarios worth tracking | Choose topics, competitors, and business priorities |
| Capture | Collects AI answer outputs, mentions, citations, and response patterns | Approve sources and collection cadence |
| Interpretation | Uses AI to classify presence, framing, and competitive context | Set rules and success criteria |
| Governance | Flags risky, inaccurate, or high-impact visibility issues | Review and escalate meaningful findings |
| Action | Routes insights into content, brand, SEO, and leadership workflows | Decide what changes to make |
The key idea is simple: measure AI visibility as a repeatable workflow, not a random screenshot habit.
Which tools and systems are involved
A practical stack might include:
Orchestration: n8n
Prompt and answer capture: browser automation, manual review queue, or platform APIs where available
Storage: Airtable, Notion, Google Sheets, or a database
Analytics inputs: branded search trends, Search Console, CRM notes, direct traffic patterns
LLM layer: one fast model for classification and one stronger model for nuanced framing analysis
Review layer: Slack, Notion, Airtable, or an internal strategy queue
Reporting destination: dashboard, weekly digest, executive briefing, or content backlog
Why n8n? Because this is not a reporting template problem. It is an orchestration problem. You need scheduled runs, normalization, branching logic, structured outputs, approvals, and handoffs. The model helps. The workflow is the product.
Where AI adds leverage
AI is useful here for classification and summarization, not for deciding what your brand should stand for.
It can:
classify whether your brand appears in an answer
detect whether you are cited, paraphrased, or omitted
score framing as favorable, neutral, or risky
compare your presence against competitors
group similar prompt outcomes into trends
summarize where visibility is growing or slipping
draft a review-ready insight report for humans
This gets even more practical when you route work by task type. Fast lower-cost models can handle repetitive classification, while stronger current models such as OpenAI’s GPT-5.6 family can step in for thornier framing analysis and edge cases. Nobody should be manually reading hundreds of AI answers and building a pattern report in a spreadsheet like it is a punishment from the old internet gods.
Where humans must stay in control
defining which prompts represent meaningful buyer journeys
choosing which competitors matter
deciding what counts as a strong or weak brand mention
reviewing reputationally sensitive misrepresentations
setting thresholds for content or brand response
connecting visibility signals to actual business goals
If your workflow turns one weird chatbot answer into a full-blown content strategy pivot with no human review, that is not measurement. That is panic with automation.
Guardrails to define before launch
| Guardrail | Implementation | Why it matters |
|---|---|---|
| Approved prompt library | Track only prompts tied to business-relevant intents and categories | Prevents noise and vanity tracking |
| Observed versus inferred fields | Store raw answer text separately from AI classification | Prevents speculation laundering |
| Human review thresholds | Require review for inaccurate, sensitive, or high-visibility findings | Protects strategy and trust |
Also useful:
log the exact prompt wording used
track which model or platform produced the answer
timestamp each capture so trends can be compared over time
use competitor tagging consistently
do not let one model score its own output without checks
The workflow blueprint
Step 1: Define the prompt universe first
Do not start by collecting random AI answers. Start by mapping real business intent.
Create prompt groups such as:
category education queries
comparison queries
best tool or vendor queries
problem-solution queries
brand-specific queries
post-purchase or implementation queries
Each group should reflect a real moment in the buyer journey. If the prompt would never matter to sales, marketing, or product, it probably does not belong in your measurement set.
Step 2: Build a normalized answer capture object
Before AI interprets anything, structure the raw data.
{
  "prompt_id": "",
  "prompt_group": "comparison_query",
  "prompt_text": "",
  "platform": "",
  "answer_text": "",
  "citations": [""],
  "competitors_mentioned": [""],
  "brand_mentioned": true,
  "capture_type": "manual|automated",
  "risk_tier": "low|medium|high"
}
This gives the workflow something usable instead of a pile of screenshots and vibes.
Step 3: Classify visibility using a clear framework
A useful reporting model tracks four dimensions:
Presence: did your brand appear at all?
Prominence: how central was the mention?
Portrayal: how was the brand framed?
Persuasion: did the answer imply you were a credible choice?
Yes, this sounds slightly academic. Good. You want a framework sturdy enough to survive an executive meeting.
Your AI step can return structured output like this:
{
  "presence_score": 0,
  "prominence_score": 0,
  "portrayal": "positive|neutral|negative|inaccurate",
  "persuasion_strength": "low|medium|high",
  "brand_role": "cited|mentioned|paraphrased|omitted",
  "competitive_position": "leading|shared|absent",
  "reasoning_notes": [""],
  "human_review_required": true
}
This turns a messy answer into something your systems can compare over time.
Step 4: Route risky findings to humans
Not every result needs a strategy meeting. Some absolutely do.
| Risk tier | Automation default | Human involvement |
|---|---|---|
| Low | Auto-classify and include in trend reporting | Spot checks |
| Medium | Classify and flag for content or SEO review | Direct review before action |
| High | Classify and halt | Brand, legal, or leadership review |
Examples of high-risk findings include inaccurate product claims, incorrect pricing references, competitor misinformation, or brand portrayal that could affect trust.
Step 5: Connect visibility to business signals
AI visibility reporting gets much more useful when it is not trapped in its own little analytics terrarium.
Join visibility data with:
branded search changes
direct traffic shifts
sales call mentions
CRM notes from inbound leads
changes in conversion by topic cluster
This is how you move from “the chatbot mentioned us” to “that mention appears to be influencing actual demand.”
Step 6: Route outputs into action queues
The workflow should not end at a dashboard.
Useful downstream actions include:
create a content refresh task when visibility is weak for high-value prompts
flag a positioning issue when competitor portrayal is stronger than yours
open a brand review when AI answers misstate your offer
generate an executive digest for weekly visibility movement
This is the difference between reporting and operations.
What this looks like in n8n
Schedule Trigger for daily or weekly runs
Prompt library pull from Airtable, Notion, or Sheets
Answer capture from approved collection method
Set or Function node for normalization
LLM node for structured visibility classification
JSON validation step
IF and Switch nodes for risk routing
Create review tasks in Slack, Airtable, or Notion
Join with analytics or CRM context where available
Write results to dashboard source and action backlog
How to choose models without becoming a benchmark goblin
| Use case | Best fit | Why |
|---|---|---|
| Basic mention detection | Fast lower-cost model | Cheap structured classification at scale |
| Framing and portrayal analysis | Balanced model | Better nuance for brand context |
| High-risk interpretation | Stronger reasoning model | Better abstention and edge-case handling |
You do not need your fanciest model to notice your brand was absent from an answer. Save the expensive thinking for messy interpretation, not routine counting. If you want a deeper workflow-first take on model routing, COEY recently covered that shift in How to Build Trusted AI Personalization Workflows.
How to measure success
| Metric | What to measure | Why it matters |
|---|---|---|
| Prompt coverage rate | Percent of tracked prompt set captured and classified consistently | Shows workflow reliability |
| Visibility share | Rate of brand presence across priority prompts versus competitors | Shows market discoverability |
| Action usefulness | Percent of routed findings that lead to meaningful content or strategy changes | Shows business value |
You should also track operational metrics:
time from capture to reviewed insight
false-alarm rate on risky findings
cost per classified answer set
change in visibility after content updates
If the workflow produces pretty charts but no strategic action, congrats, you built decorative analytics.
Tradeoffs and constraints
AI answers change often, so consistency requires disciplined prompt sets
not every platform offers easy or official access for collection
visibility signals can be directional before they are decision-grade
competitive interpretation still requires human judgment
brand mentions without business impact should not hijack strategy
Also worth saying out loud: you are not trying to game every answer box on the internet. You are trying to understand how your brand is being represented so you can improve the systems that feed discoverability.
Why this is really a systems problem
Anyone can manually check a few prompts and post a screenshot in Slack.
The hard part is building a system where prompts, answer captures, brand classifications, review thresholds, analytics context, and action routing all stay connected.
That is not a dashboard trick. That is systems design.
Humans still define what matters, what representation is acceptable, and what the brand should do next. AI helps collect and compress the signal. Automation makes the discipline repeatable.
Humans define the visibility strategy. AI organizes the mess. Systems make it actionable.
That is how you build an AI visibility reporting workflow that helps marketers and executives move from curiosity to execution, without mistaking noisy answer surfaces for strategy itself.